The post Types of quantitative methods appeared first on HKT Consultant.
]]>Quantitative methods represent the steps of using the Scientific Method of research. There are following types of quantitative method…
1. Experimental Research is the most well-established quantitative methodology in both the physical and social sciences. This approach uses the principles of research in the physical sciences to conduct experiments that explore human behavior.
2. Survey Research is used to ask people a number of questions about particular topics. Surveys can be online, mailed, handed out, or conducted in interview format. After researchers have collected survey data, they represent participants’ responses in numerical form using tables, graphs, charts, and/or percentages.
3. Content Analysis. Researchers use content analysis to count the number of occurrences of their particular focus of inquiry. Communication researchers often conduct content analyses of movies, commercials, television shows, magazines, etc., to count the number of occurrences of particular phenomena in these contexts to explore potential effects.
4. Meta-Analysis. Do you ever get frustrated when you hear about one research project that says a particular food is good for your health, and then some time later, you hear about another research project that says the opposite? Meta-analysis analyzes existing statistics found in a collection of quantitative research to demonstrate patterns in a particular line of research over time.
The post Types of quantitative methods appeared first on HKT Consultant.
]]>The post Questionnaire survey for quantitative research appeared first on HKT Consultant.
]]>Survey vs Questionnaire: Differences and Definitions
A questionnaire is used to collect data from a list of questions. It’s not used to look for trends, behavior or a bigger picture. A survey is data collection through a set of questions for the purposes of statistical analysis
A survey involves gathering data to use for analysis and forecasting. As opposed to its questionnaire cousin, the data isn’t analyzed in isolation. Surveys do look for trends, behavior, and the bigger picture.
Here’s another way to put it: A questionnaire is one-purpose data collection through a set of questions. A survey is data collection through a set of questions for the purposes of statistical analysis.
The definition of a questionnaire
Here’s an example of a questionnaire. Flashback to the last time you joined a gym, maybe you went for a health check when you signed up. You would have been asked to answer a list of specific questions about medical history.
That was a questionnaire. The information you provided is used to assess risk, help with diagnoses and paint a picture of your medical history. It’s not used to look for trends, behavior or a bigger picture.
The definition of a survey
Think of a survey as a major project, aimed at using data to reach informed conclusions. Yes, that’s right – a survey could be regarded as a questionnaire on steroids.
With a survey, you can dig deeper and find out peoples’ opinions and ideas. You can ask demographic survey questions, you can find out how engaged your employees are, or you can do market research. And much more.
Main contentsSee more from basic to advanced


Why do people mix up the two?
Well, it’s simple—they’re very similar. In fact, a big part of any survey involves a questionnaire. Marketing professionals and research specialists have always differentiated the two, but things have changed since the advent of the Internet. As more individuals and organizations started to manage their own research projects, the two terms became interchangeable.
“Survey” has become a synonym for “questionnaire”—and vice versa.
Now, just to dial your level of confusion up to 11, there’s also such a thing as a survey questionnaire. It starts as a simple questionnaire but later transforms into a survey—mindblown.
Imagine you’re trying to gauge how your employees feel about working with you. By using Likert Scale Questionnaires, you can ask people to express their feelings on a scale of, say, one to five. Then by aggregating the scores, you can get an overall picture of satisfaction levels within your organization.
Advantages of questionnaires include increased speed of data collection, low or no cost requirements, and higher levels of objectivity compared to many alternative methods of primary data collection. However, questionnaires have certain disadvantages such as selection of random answer choices by respondents without properly reading the question. Moreover, there is usually no possibility for respondents to express their additional thoughts about the matter due to the absence of a relevant question.
There are following types of questionnaires
Computer questionnaire. Respondents are asked to answer the questionnaire which is sent by mail. The advantages of the computer questionnaires include their inexpensive price, time-efficiency, and respondents do not feel pressured, therefore can answer when they have time, giving more accurate answers. However, the main shortcoming of the mail questionnaires is that sometimes respondents do not bother answering them and they can just ignore the questionnaire.
Telephone questionnaire. Researcher may choose to call potential respondents with the aim of getting them to answer the questionnaire. The advantage of the telephone questionnaire is that, it can be completed during the short amount of time. The main disadvantage of the phone questionnaire is that it is expensive most of the time. Moreover, most people do not feel comfortable to answer many questions asked through the phone and it is difficult to get sample group to answer questionnaire over the phone.
In-house survey. This type of questionnaire involves the researcher visiting respondents in their houses or workplaces. The advantage of in-house survey is that more focus towards the questions can be gained from respondents. However, in-house surveys also have a range of disadvantages which include being time consuming, more expensive and respondents may not wish to have the researcher in their houses or workplaces for various reasons.
Mail Questionnaire. This sort of questionnaires involve the researcher to send the questionnaire list to respondents through post, often attaching pre-paid envelope. Mail questionnaires have an advantage of providing more accurate answer, because respondents can answer the questionnaire in their spare time. The disadvantages associated with mail questionnaires include them being expensive, time consuming and sometimes they end up in the bin put by respondents.
Questionnaires can include the following types of questions:
Open question questionnaires. Open questions differ from other types of questions used in questionnaires in a way that open questions may produce unexpected results, which can make the research more original and valuable. However, it is difficult to analyze the results of the findings when the data is obtained through the questionnaire with open questions.
Multiple choice questions. Respondents are offered a set of answers they have to choose from. The downsize of questionnaire with multiple choice questions is that, if there are too many answers to choose from, it makes the questionnaire, confusing and boring, and discourages the respondent to answer the questionnaire.
Dichotomous Questions. This type of questions gives two options to respondents – yes or no, to choose from. It is the easiest form of questionnaire for the respondent in terms of responding it.
Scaling Questions. Also referred to as ranking questions, they present an option for respondents to rank the available answers to the questions on the scale of given range of values (for example from 1 to 10).
Survey Monkey represents one of the most popular online platforms for facilitating data collection through questionnaires. Substantial benefits offered by Survey Monkey include its ease to use, presentation of questions in many different formats and advanced data analysis capabilities.
The post Questionnaire survey for quantitative research appeared first on HKT Consultant.
]]>The post Content Analysis Method and Examples appeared first on HKT Consultant.
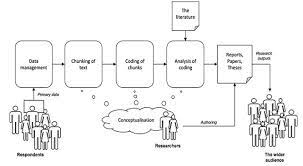
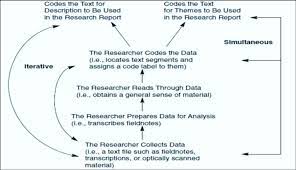
]]>Sources of data could be from interviews, open-ended questions, field research notes, conversations, or literally any occurrence of communicative language (such as books, essays, discussions, newspaper headlines, speeches, media, historical documents). A single study may analyze various forms of text in its analysis. To analyze the text using content analysis, the text must be coded, or broken down, into manageable code categories for analysis (i.e. “codes”). Once the text is coded into code categories, the codes can then be further categorized into “code categories” to summarize data even further.
Main contentsSee more from basic to advanced
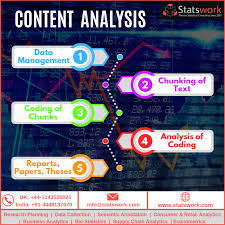
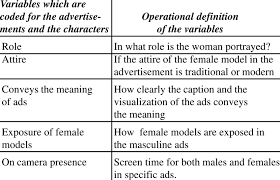
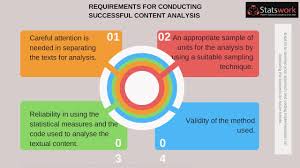
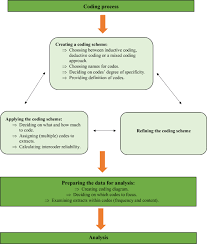
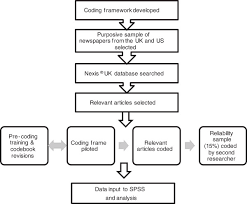
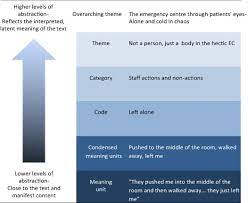
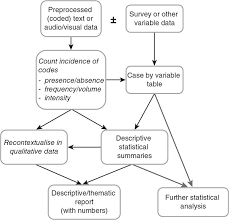
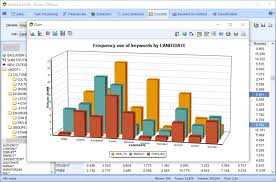
Quantitative content analysis highlights frequency counts and objective analysis of these coded frequencies. Additionally, quantitative content analysis begins with a framed hypothesis with coding decided on before the analysis begins. These coding categories are strictly relevant to the researcher’s hypothesis. Quantitative analysis also takes a deductive approach.
Siegfried Kracauer provides a critique of quantitative analysis, asserting that it oversimplifies complex communications in order to be more reliable. On the other hand, qualitative analysis deals with the intricacies of latent interpretations, whereas quantitative has a focus on manifest meanings. He also acknowledges an “overlap” of qualitative and quantitative content analysis. Patterns are looked at more closely in qualitative analysis, and based on the latent meanings that the researcher may find, the course of the research could be changed. It is inductive and begins with open research questions, as opposed to a hypothesis.
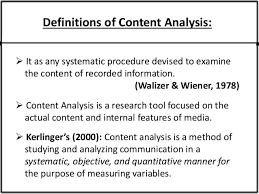
Three different definition of content analysis are provided below.
- Definition 1: “Any technique for making inferences by systematically and objectively identifying special characteristics of messages.” (from Holsti, 1968)
- Definition 2: “An interpretive and naturalistic approach. It is both observational and narrative in nature and relies less on the experimental elements normally associated with scientific research (reliability, validity and generalizability) (from Ethnography, Observational Research, and Narrative Inquiry, 1994-2012).
- Definition 3: “A research technique for the objective, systematic and quantitative description of the manifest content of communication.” (from Berelson, 1952)
Uses of Content Analysis
- Identify the intentions, focus or communication trends of an individual, group or institution
- Describe attitudinal and behavioral responses to communications
- Determine psychological or emotional state of persons or groups
- Reveal international differences in communication content
- Reveal patterns in communication content
- Pre-test and improve an intervention or survey prior to launch
- Analyze focus group interviews and open-ended questions to complement quantitative data
Types of Content Analysis
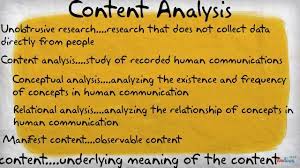
There are two general types of content analysis: conceptual analysis and relational analysis. Conceptual analysis determines the existence and frequency of concepts in a text. Relational analysis develops the conceptual analysis further by examining the relationships among concepts in a text. Each type of analysis may lead to different results, conclusions, interpretations and meanings.
Conceptual Analysis
Typically people think of conceptual analysis when they think of content analysis. In conceptual analysis, a concept is chosen for examination and the analysis involves quantifying and counting its presence. The main goal is to examine the occurrence of selected terms in the data. Terms may be explicit or implicit. Explicit terms are easy to identify. Coding of implicit terms is more complicated: you need to decide the level of implication and base judgments on subjectivity (issue for reliability and validity). Therefore, coding of implicit terms involves using a dictionary or contextual translation rules or both.
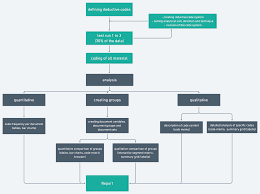
To begin a conceptual content analysis, first identify the research question and choose a sample or samples for analysis. Next, the text must be coded into manageable content categories. This is basically a process of selective reduction. By reducing the text to categories, the researcher can focus on and code for specific words or patterns that inform the research question.
General steps for conducting a conceptual content analysis:
1. Decide the level of analysis: word, word sense, phrase, sentence, themes
2. Decide how many concepts to code for: develop pre-defined or interactive set of categories or concepts. Decide either: A. to allow flexibility to add categories through the coding process, or B. to stick with the pre-defined set of categories.
- Option A allows for the introduction and analysis of new and important material that could have significant implications to one’s research question.
- Option B allows the researcher to stay focused and examine the data for specific concepts.
3. Decide whether to code for existence or frequency of a concept. The decision changes the coding process.
- When coding for the existence of a concept, the researcher would count a concept only once if it appeared at least once in the data and no matter how many times it appeared.
- When coding for the frequency of a concept, the researcher would count the number of times a concept appears in a text.
4. Decide on how you will distinguish among concepts:
- Should text be coded exactly as they appear or coded as the same when they appear in different forms? For example, “dangerous” vs. “dangerousness”. The point here is to create coding rules so that these word segments are transparently categorized in a logical fashion. The rules could make all of these word segments fall into the same category, or perhaps the rules can be formulated so that the researcher can distinguish these word segments into separate codes.
- What level of implication is to be allowed? Words that imply the concept or words that explicitly state the concept? For example, “dangerous” vs. “the person is scary” vs. “that person could cause harm to me”. These word segments may not merit separate categories, due the implicit meaning of “dangerous”.
5. Develop rules for coding your texts. After decisions of steps 1-4 are complete, a researcher can begin developing rules for translation of text into codes. This will keep the coding process organized and consistent. The researcher can code for exactly what he/she wants to code. Validity of the coding process is ensured when the researcher is consistent and coherent in their codes, meaning that they follow their translation rules. In content analysis, obeying by the translation rules is equivalent to validity.
6. Decide what to do with irrelevant information: should this be ignored (e.g. common English words like “the” and “and”), or used to reexamine the coding scheme in the case that it would add to the outcome of coding?
7. Code the text: This can be done by hand or by using software. By using software, researchers can input categories and have coding done automatically, quickly and efficiently, by the software program. When coding is done by hand, a researcher can recognize error far more easily (e.g. typos, misspelling). If using computer coding, text could be cleaned of errors to include all available data. This decision of hand vs. computer coding is most relevant for implicit information where category preparation is essential for accurate coding.
8. Analyze your results: Draw conclusions and generalizations where possible. Determine what to do with irrelevant, unwanted or unused text: reexamine, ignore, or reassess the coding scheme. Interpret results carefully as conceptual content analysis can only quantify the information. Typically, general trends and patterns can be identified.
Relational Analysis
Relational analysis begins like conceptual analysis, where a concept is chosen for examination. However, the analysis involves exploring the relationships between concepts. Individual concepts are viewed as having no inherent meaning and rather the meaning is a product of the relationships among concepts.
To begin a relational content analysis, first identify a research question and choose a sample or samples for analysis. The research question must be focused so the concept types are not open to interpretation and can be summarized. Next, select text for analysis. Select text for analysis carefully by balancing having enough information for a thorough analysis so results are not limited with having information that is too extensive so that the coding process becomes too arduous and heavy to supply meaningful and worthwhile results.
There are three subcategories of relational analysis to choose from prior to going on to the general steps.
- Affect extraction: an emotional evaluation of concepts explicit in a text. A challenge to this method is that emotions can vary across time, populations, and space. However, it could be effective at capturing the emotional and psychological state of the speaker or writer of the text.
- Proximity analysis: an evaluation of the co-occurrence of explicit concepts in the text. Text is defined as a string of words called a “window” that is scanned for the co-occurrence of concepts. The result is the creation of a “concept matrix”, or a group of interrelated co-occurring concepts that would suggest an overall meaning.
- Cognitive mapping: a visualization technique for either affect extraction or proximity analysis. Cognitive mapping attempts to create a model of the overall meaning of the text such as a graphic map that represents the relationships between concepts.
General steps for conducting a relational content analysis:
1. Determine the type of analysis: Once the sample has been selected, the researcher needs to determine what types of relationships to examine and the level of analysis: word, word sense, phrase, sentence, themes.
2. Reduce the text to categories and code for words or patterns. A researcher can code for existence of meanings or words.
3. Explore the relationship between concepts: once the words are coded, the text can be analyzed for the following:
- Strength of relationship: degree to which two or more concepts are related.
- Sign of relationship: are concepts positively or negatively related to each other?
- Direction of relationship: the types of relationship that categories exhibit. For example, “X implies Y” or “X occurs before Y” or “if X then Y” or if X is the primary motivator of Y.
4. Code the relationships: a difference between conceptual and relational analysis is that the statements or relationships between concepts are coded.
5. Perform statistical analyses: explore differences or look for relationships among the identified variables during coding.
6. Map out representations: such as decision mapping and mental models.
Reliability and Validity
Reliability: Because of the human nature of researchers, coding errors can never be eliminated but only minimized. Generally, 80% is an acceptable margin for reliability. Three criteria comprise the reliability of a content analysis:
- Stability: the tendency for coders to consistently re-code the same data in the same way over a period of time.
- Reproducibility: tendency for a group of coders to classify categories membership in the same way.
- Accuracy: extent to which the classification of text corresponds to a standard or norm statistically.
Validity: Three criteria comprise the validity of a content analysis:
- Closeness of categories: this can be achieved by utilizing multiple classifiers to arrive at an agreed upon definition of each specific category. Using multiple classifiers, a concept category that may be an explicit variable can be broadened to include synonyms or implicit variables.
- Conclusions: What level of implication is allowable? Do conclusions correctly follow the data? Are results explainable by other phenomena? This becomes especially problematic when using computer software for analysis and distinguishing between synonyms. For example, the word “mine,” variously denotes a personal pronoun, an explosive device, and a deep hole in the ground from which ore is extracted. Software can obtain an accurate count of that word’s occurrence and frequency, but not be able to produce an accurate accounting of the meaning inherent in each particular usage. This problem could throw off one’s results and make any conclusion invalid.
- Generalizability of the results to a theory: dependent on the clear definitions of concept categories, how they are determined and how reliable they are at measuring the idea one is seeking to measure. Generalizability parallels reliability as much of it depends on the three criteria for reliability.
Advantages of Content Analysis
- Directly examines communication using text
- Allows for both qualitative and quantitative analysis
- Provides valuable historical and cultural insights over time
- Allows a closeness to data
- Coded form of the text can be statistically analyzed
- Unobtrusive means of analyzing interactions
- Provides insight into complex models of human thought and language use
- When done well, is considered a relatively “exact” research method
- Content analysis is a readily-understood and an inexpensive research method
- A more powerful tool when combined with other research methods such as interviews, observation, and use of archival records. It is very useful for analyzing historical material, especially for documenting trends over time.
Disadvantages of Content Analysis
- Can be extremely time consuming
- Is subject to increased error, particularly when relational analysis is used to attain a higher level of interpretation
- Is often devoid of theoretical base, or attempts too liberally to draw meaningful inferences about the relationships and impacts implied in a study
- Is inherently reductive, particularly when dealing with complex texts
- Tends too often to simply consist of word counts
- Often disregards the context that produced the text, as well as the state of things after the text is produced
-
Can be difficult to automate or computerize
The post Content Analysis Method and Examples appeared first on HKT Consultant.
]]>The post Introduction to Statistical Data Analysis appeared first on HKT Consultant.
]]>Statistics is basically a science that involves data collection, data interpretation and finally, data validation. Statistical data analysis is a procedure of performing various statistical operations. It is a kind of quantitative research, which seeks to quantify the data, and typically, applies some form of statistical analysis. Quantitative data basically involves descriptive data, such as survey data and observational data.
Statistical data analysis generally involves some form of statistical tools, which a layman cannot perform without having any statistical knowledge. There are various software packages to perform statistical data analysis. This software includes Statistical Package for the Social Sciences (SPSS), Stata soft, etc.
Data in statistical data analysis consists of variable(s). Sometimes the data is univariate or multivariate. Depending upon the number of variables, the researcher performs different statistical techniques.
Main contentsSee more from basic to advanced
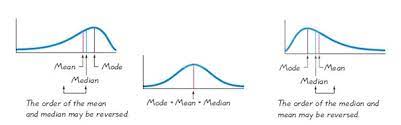
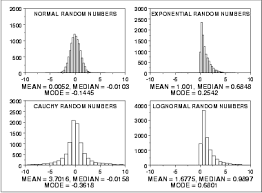
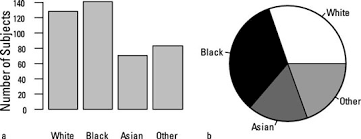
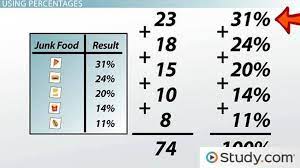
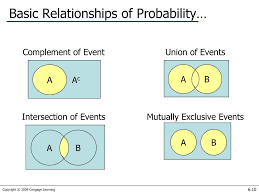
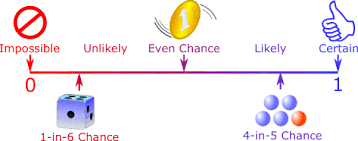
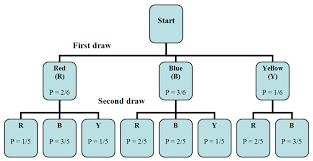
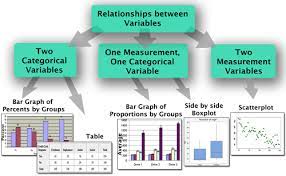
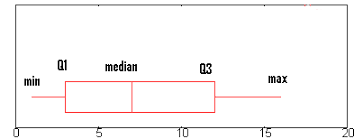
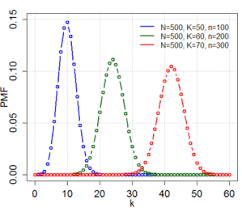
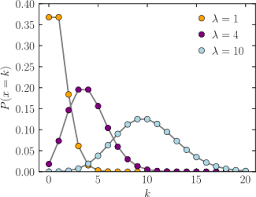
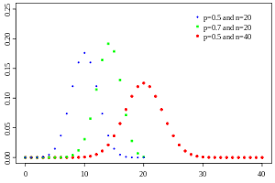
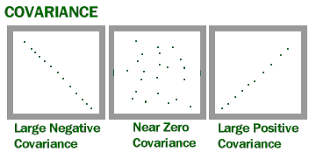
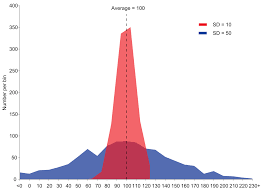
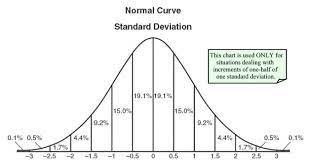
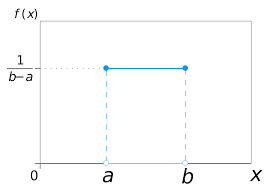
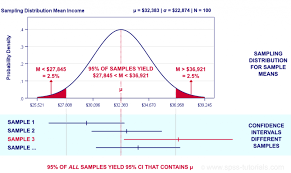
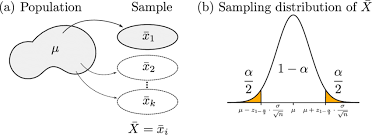
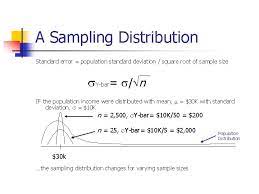
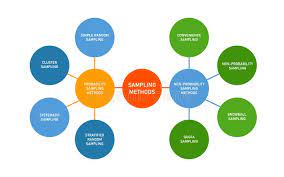
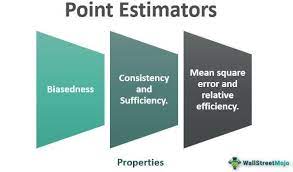
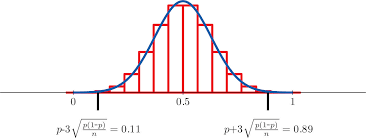
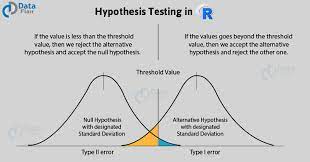
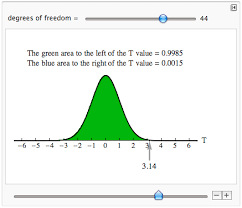
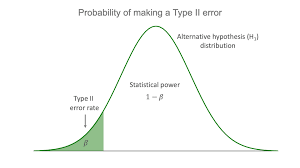
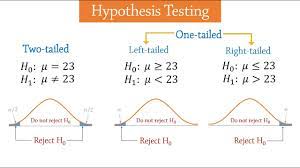
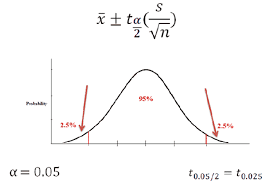
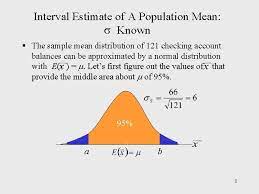
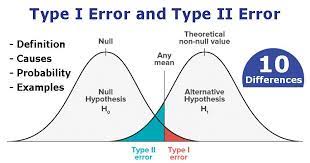
If the data in statistical data analysis is multiple in numbers, then several multivariates can be performed. These are factor statistical data analysis, discriminant statistical data analysis, etc. Similarly, if the data is singular in number, then the univariate statistical data analysis is performed. This includes t test for significance, z test, f test, ANOVA one way, etc.
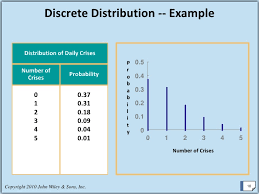
The data in statistical data analysis is basically of 2 types, namely, continuous data and discreet data. The continuous data is the one that cannot be counted. For example, intensity of a light can be measured but cannot be counted. The discreet data is the one that can be counted. For example, the number of bulbs can be counted.
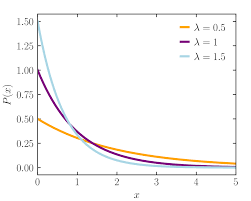
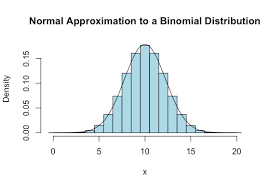
The continuous data in statistical data analysis is distributed under continuous distribution function, which can also be called the probability density function, or simply pdf.
The discreet data in statistical data analysis is distributed under discreet distribution function, which can also be called the probability mass function or simple pmf.
We use the word ‘density’ in continuous data of statistical data analysis because density cannot be counted, but can be measured. We use the word ‘mass’ in discreet data of statistical data analysis because mass cannot be counted.
There are various pdf’s and pmf’s in statistical data analysis. For example, Poisson distribution is the commonly known pmf, and normal distribution is the commonly known pdf.
These distributions in statistical data analysis help us to understand which data falls under which distribution. If the data is about the intensity of a bulb, then the data would be falling in Poisson distribution.
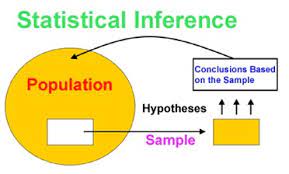
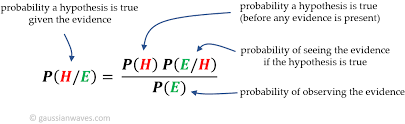
There is a major task in statistical data analysis, which comprises of statistical inference. The statistical inference is mainly comprised of two parts: estimation and tests of hypothesis.
Estimation in statistical data analysis mainly involves parametric data—the data that consists of parameters. On the other hand, tests of hypothesis in statistical data analysis mainly involve non parametric data— the data that consists of no parameters.
The post Introduction to Statistical Data Analysis appeared first on HKT Consultant.
]]>The post Meta-analysis in management research appeared first on HKT Consultant.
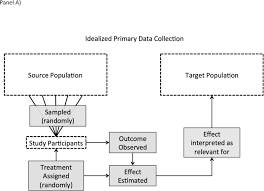
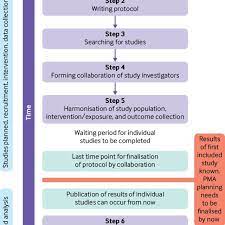
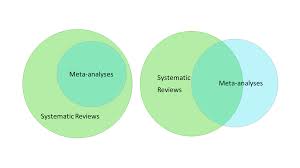
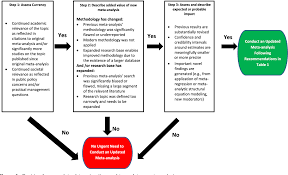
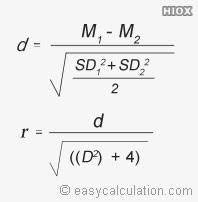
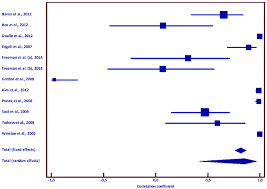
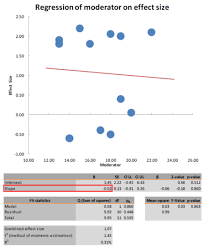
]]>“Meta-analysis is the statistical combination of results from two or more separate studies” (Deeks et al, 2019, chapter 10). When the treatment effect (or effect size) is consistent from one study to the next, meta-analysis can be used to identify this common effect. When the effect varies from one study to the next, meta-analysis may be used to identify the reason for the variation.
Decisions about the utility of an intervention or the validity of a hypothesis cannot be based on the results of a single study, because results typically vary from one study to the next. Rather, a mechanism is needed to synthesize data across studies. Narrative reviews had been used for this purpose, but the narrative review is largely subjective (different experts can come to different conclusions) and becomes impossibly difficult when there are more than a few studies involved. Meta-analysis, by contrast, applies objective formulas (much as one would apply statistics to data within a single study), and can be used with any number of studies.
Pharmaceutical companies use meta-analysis to gain approval for new drugs, with regulatory agencies sometimes requiring a meta-analysis as part of the approval process. Clinicians and applied researchers in medicine, education, psychology, criminal justice, and a host of other fields use meta-analysis to determine which interventions work, and which ones work best. Meta analysis is also widely used in basic research to evaluate the evidence in areas as diverse as sociology, social psychology, sex differences, finance and economics, political science, marketing, ecology and genetics, among others.
Main contentsSee more from basic to advanced





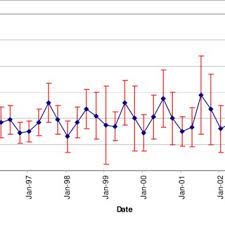
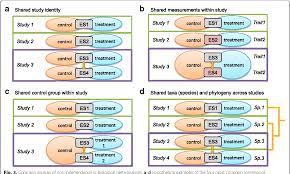
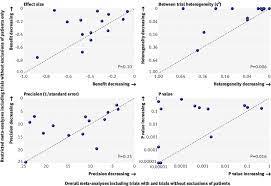
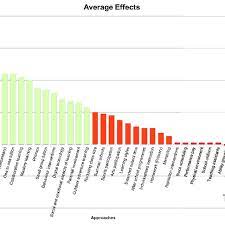
Where does meta-analysis fit in the research process?
Publications
Many journals encourage researchers to submit systematic reviews and meta-analyses that summarize the body of evidence on a specific question, and this approach is replacing the traditional narrative review. Meta-analyses also play supporting roles in other papers. For example, a paper that reports results for a new primary study might include a meta-analysis in the introduction to synthesize prior data and help to place the new study in context.
Planning new studies
Meta-analyses can play a key role in planning new studies. The meta-analysis can help identify which questions have already been answered and which remain to be answered, which outcome measures or populations are most likely to yield significant results, and which variants of the planned intervention are likely to be most powerful.
Grant applications
Meta-analyses are used in grant applications to justify the need for a new study. The meta-analysis serves to put the available data in context and to show the potential utility of the planned study. The graphical elements of the meta-analysis, such as the forest plot, provide a mechanism for presenting the data clearly, and for capturing the attention of the reviewers. Some funding agencies now require a meta-analysis of existing research as part of the grant application to fund new research.
The post Meta-analysis in management research appeared first on HKT Consultant.
]]>The post A Definition of Content Analysis appeared first on HKT Consultant.
]]>The classification process, called “coding,” consists of marking text passages with short alphanumeric codes. This creates “categorical variables” that represent the original, verbal information and that can then be analyzed by standard statistical methods. The text passages can come from structured interviews, focus group discussions, case studies, open-ended questions on survey instruments, workpapers, agency documents, and previous evaluations. 1 Content analysis is particularly useful in GAO work because of the large quantity of written material that evaluators typically collect during a project, especially when it
comes from diverse and unstructured sources.
To classify a document’s key ideas, the evaluator identifies its themes, issues, topics, and so on. Theresult might be a simple list of the topics in a series of meeting notes. Content analysis can go further if theevaluator counts the frequency of statements, detects subtle differences in their intensity, or examines issues over time, in different situations, or from different groups.
Thus, content analysis can not only help summarize the formal content of written material; it can also describe the attitudes or perceptions of the author of that material. For example, if an evaluator wanted to assess the effects of a program on the lives of older people from their perspective, he or she could analyze open-ended interview responses to determine their outlook on life, loneliness, or security. Similarly, an evaluator could assess the effect of Voice of America broadcasts by analyzing the content of Soviet newspaper articles and radio broadcasts. (Inkeles, 1952)
Source: GAO (2013), Content Analysis: A Methodology for Structuring and Analyzing Written Material: PEMD-10.3.1, BiblioGov.
The post A Definition of Content Analysis appeared first on HKT Consultant.
]]>The post The Uses of Content Analysis appeared first on HKT Consultant.
]]>- In Stars and Stripes: Inherent Conflicts Lead to Allegations of Military Censorship (GAO, 1988), GAO evaluators used content analysis to help assess issues of censorship, news management, and other influences on various editions of the military newspaper. Details of technique and substance from this report are used as examples throughout this transfer paper.
- In Student Loans: Direct Loans Could Save Billions in First 5 Years With Proper Implementation (GAO, 1992c), GAO evaluators examined transcripts of focus groups discussing the difficulty of implementing a student loan program. The participants’ views on whether the Department of Education could administer a direct loan program were mixed, but the evaluators were able, through content analysis, to highlight the dominant views and the reasons for them.
- Federal Employment: How Federal Employees View the Government As a Place to Work (GAO, 1992a) reported that while the majority of the survey respondents looked favorably on working for the government, many did not. The evaluators used content analysis to assess the respondent’s insightful, written comments to open-ended questions. An appendix in the report is devoted to the analysis of these comments.
- Another excellent example of the use of content analysis appears in Women in the Military: Deployment in the Persian Gulf War (GAO, 1993c). For this study, the evaluators gave a primarily positive assessment of women’s performance, using content analysis to determine that while men and women endured similarly harsh encampment facilities and conditions, both men and women considered health and hygiene problems inconsequential and their cohesion in mixed-gender units effective.
- Among other fine examples of the use of content analyis is Veterans’ Health Care: Veterans’. Perceptions of VA Services and VA’s Role in Health Care Reform (GAO, 1994a). The report’s scope and methodology section details the analysis and summary of veterans’ views that changing the VA system could, among other things, diminish or eliminate their benefits as well as harm them both emotionally and in terms of their specialized health care needs.
Other uses of content analysis in GAO reports include an analysis of transcripts of focus groups on people’s ability to participate in food assistance programs (GAO, 1990), an analysis of descriptive text on the maintenance of aging aircraft (GAO, 1993a), and an analysis of open-ended discussions with Amerasian immigrants on their experiences in Vietnam, the Philippines, and the United States (GAO, 1994b).
Source: GAO (2013), Content Analysis: A Methodology for Structuring and Analyzing Written Material: PEMD-10.3.1, BiblioGov.
The post The Uses of Content Analysis appeared first on HKT Consultant.
]]>The post Computerized Content Analysis appeared first on HKT Consultant.
]]>Source: GAO (2013), Content Analysis: A Methodology for Structuring and Analyzing Written Material: PEMD-10.3.1, BiblioGov.
The post Computerized Content Analysis appeared first on HKT Consultant.
]]>The post Some Advantages of Content Analysis appeared first on HKT Consultant.
]]>One problem with surveys and some experimental methods is that evaluators and their informants can interact during data collection in ways other than how they would “naturally” react. For example, a content analysis of the hearing transcripts might be more useful than interviews with federal officials about what took place during public hearings on proposed environmental regulations. The officials might leave out important points, unconsciously or purposely, in order to protect themselves, but the transcripts provide the complete record. Thus, bias can be reduced dining data collection. Similarly, the evaluator can eliminate from analysis survey questions that might be inappropriate because they invaded a respondent’s privacy.
2. It Can Deal With Large Volumes of Material
Content analysis has explicit procedures and quality control checks that make it possible for only a few or a great number of evaluators to analyze large volumes of textual data. Furthermore, the explicit procedures and quality control checks allow two or more groups of analysts to work on the same kind of data in different geographic locations, and computer software may be used to perform many of the required steps. (See appendix II.)
3. It Is Systematic
Content analysis can help evaluators learn more about the issues and programs they examine because it is systematic. It has structured forms that allow evaluators to extract relevant information more consistently than if they were reading the same documents only casually.
4. It Can Corroborate Other Evaluation Methods
When the findings from content analysis are not the main evidence in an evaluation, they can still be used to help corroborate other findings, such as responses from closed-ended surveys or from economic measures. For example, Webb and colleagues have described how investigators can use “multiple operations” to increase confidence in their findings, although we do not discuss them in this paper. (Webb et al., 1981)
Source: GAO (2013), Content Analysis: A Methodology for Structuring and Analyzing Written Material: PEMD-10.3.1, BiblioGov.
The post Some Advantages of Content Analysis appeared first on HKT Consultant.
]]>The post Some Disadvantages of Content Analysis appeared first on HKT Consultant.
]]>Source: GAO (2013), Content Analysis: A Methodology for Structuring and Analyzing Written Material: PEMD-10.3.1, BiblioGov.
The post Some Disadvantages of Content Analysis appeared first on HKT Consultant.
]]>